Bankruptcy Case Intelligence Explained (September 2026)
You know the 6 p.m. scramble. The petition's due tomorrow, the credit report is still a stack of PDFs, and the pay stubs need keying into schedules field by field. That work is slow, and small transcription mistakes stack up into schedule errors fast. Case intelligence reads those documents as they land, pulls the facts that belong in each schedule, and hands your paralegals a populated file to review instead of a form to fill from zero.
TLDR:
- Case intelligence reads incoming documents and builds the file itself, so paralegals review data instead of keying it.
- AI parses credit reports, pay stubs, and titles; deterministic logic runs the means test so court numbers stay auditable.
- One entered value propagates across 21-plus linked petition fields, and conflicting sources surface with provenance for human review.
- Signature-date checks, district form checklists, and CM/ECF-spec PDFs catch the most common deficiency triggers before filing.
- Glade AI pre-populates 50 to 75 percent of questionnaire fields before paralegal review, collapsing 8-hour petition prep to roughly 2 hours.
What Case Intelligence Means in Bankruptcy Software
Most bankruptcy software works like a filing cabinet with a keyboard attached. A paralegal opens a case, types in the debtor's income, creditors, and assets, and the system stores whatever gets keyed in. Nothing arrives on its own.
Case intelligence describes a different behavior. The software reads the documents, forms, and records tied to a matter as they come in, pulls out the facts that matter, and builds the case file from them. A credit report, pay stubs, a bank statement, a court notice: each gets read and turned into structured case data without retyping.
The distinction boils down to who does the assembly. A plain case management database holds what a human enters. A case intelligence system does the reading and populating itself, then hands the human a file to review instead of a blank form to fill.
Why Manual Data Entry Is the Bottleneck in Bankruptcy Petition Prep
A single consumer petition runs past 50 pages of schedules, statements, and forms. Most of it gets transcribed by hand: creditors copied off the tri-merge report into Schedules D, E, and F, income keyed from pay stubs, balances read off bank statements one field at a time.
That work is slow and error-prone. Manual data entry for bankruptcy firms runs roughly three to five minutes per document at 96 to 98 percent accuracy, per Lido's general data-entry comparison. Across dozens of documents per case, small transcription mistakes accumulate into schedule errors.
Volume compounds it. Total bankruptcy filings rose 7 percent to 51,772 in May 2026, ABI reports. More cases, same keying bottleneck.
How AI Reads Bankruptcy Documents and Extracts the Facts That Matter
Extraction starts with classification, not reading. When a file lands, the software first identifies what it is: a credit report, pay stub, bank statement, mortgage statement, or vehicle title. Only then does it route the document to the right parser and schedule mapping.
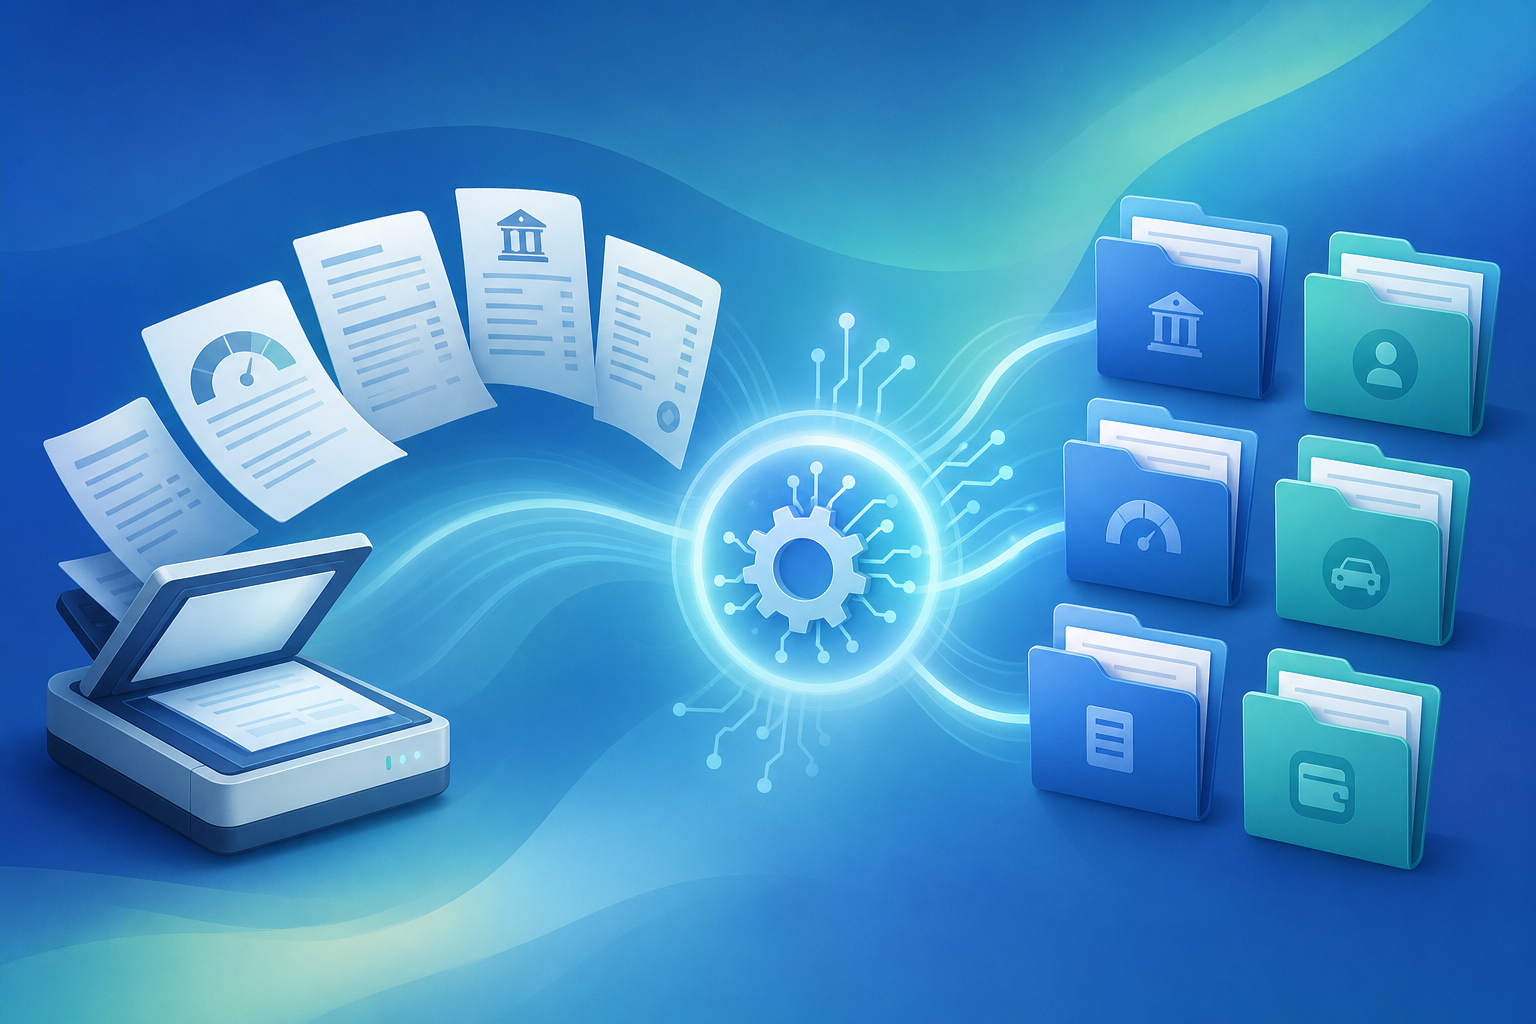
From there, the mechanics vary by document:
- Credit reports get read semantically, so each tradeline routes to Schedule D, E, or F by its function instead of the label a bureau prints. Understanding AI in bankruptcy law helps explain why semantic reading outperforms position-based parsing. Experian, TransUnion, and Equifax name fields differently; reading function over position keeps routing consistent.
- AI-powered exemptions, paystubs, and bank statements are parsed line by line for gross, taxes, retirement, and withholdings, then converted to monthly figures.
- Mortgage statements yield servicer, loan number, and where to send payment, updating one creditor record instead of duplicating it.
- Vehicle titles need OCR plus image analysis to pull VINs, plates, and low-contrast text off phone photos, with orientation corrected first.
The Difference Between AI Parsing and Deterministic Calculation
Once the facts are extracted, the work splits into two jobs with different accuracy needs. Reading a document is a pattern problem: pay stub formats vary, credit reports reorder fields, phone photos come in crooked. AI handles that variability well, because parsing and classification tolerate ambiguity.
Statutory math is the opposite. The means test, six-month income averaging, and state exemption limits run on fixed formulas against published thresholds. Those calculations need to be reproducible and traceable to the exact rule that produced them, because a trustee or judge can check the arithmetic.
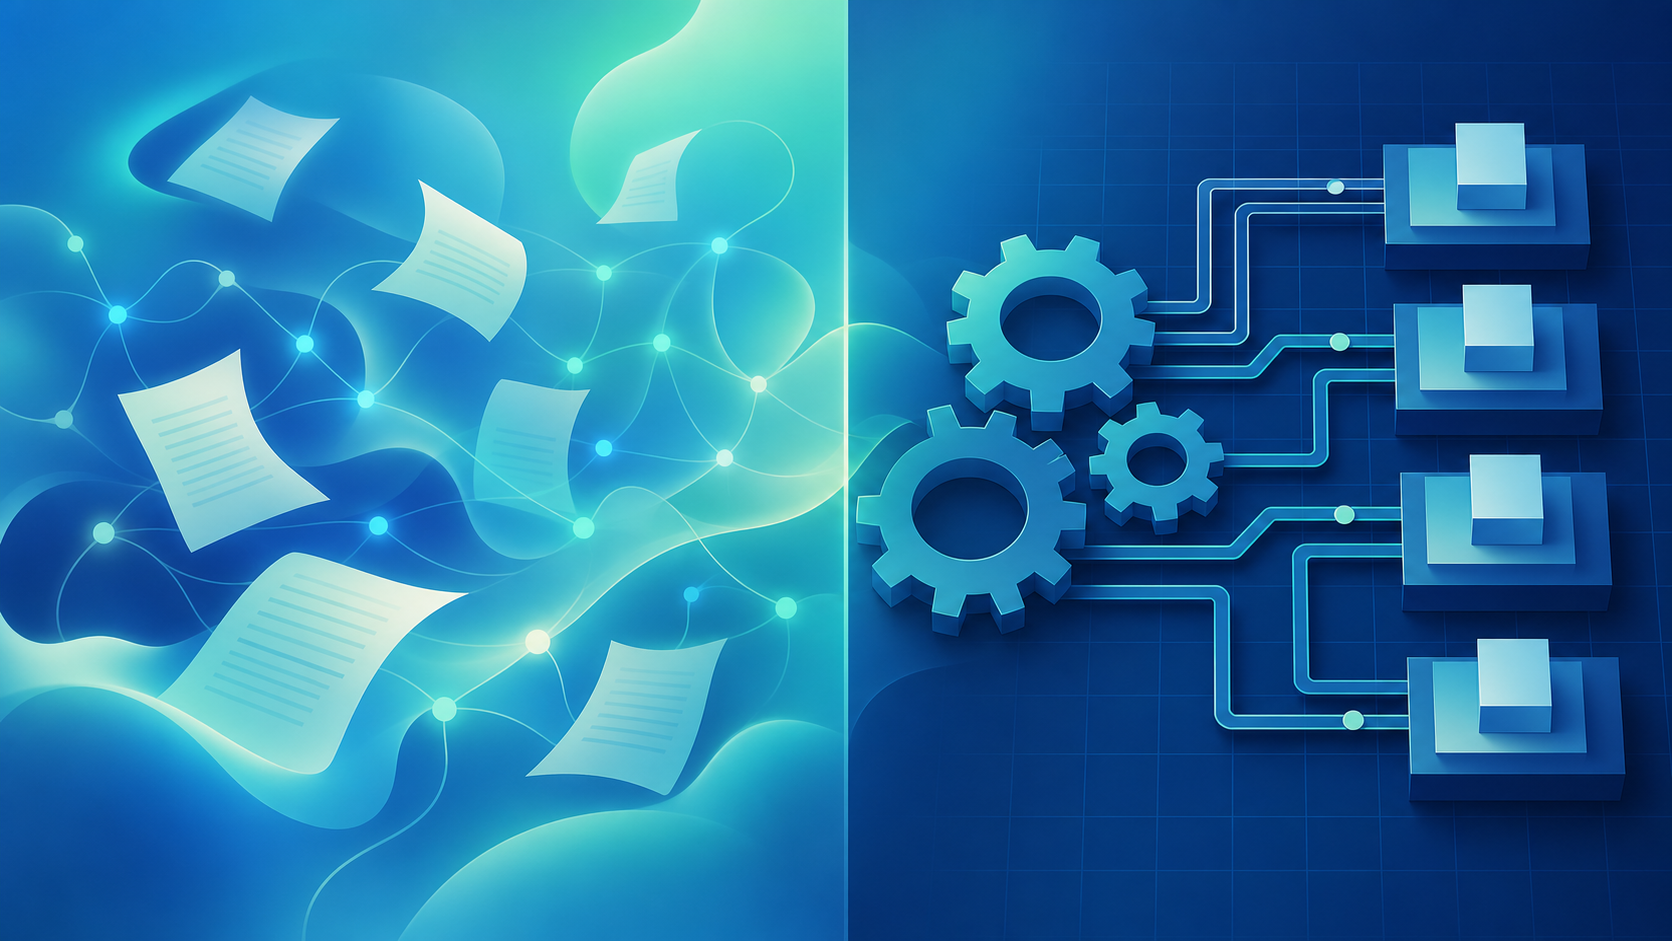
So the line for the category is clear: let AI read the documents, but run the court-filed numbers on deterministic, rule-based logic. An LLM guessing at a means-test result cannot be audited the way a fixed formula can.
Dimension | AI Parsing | Deterministic Calculation |
|---|---|---|
Job | Reading documents | Statutory math |
Handles | Varying pay stub formats, reordered credit report fields, crooked phone photos | Means test, six-month income averaging, state exemption limits |
Tolerance for ambiguity | High: parsing and classification tolerate ambiguity | None: runs on fixed formulas against published thresholds |
Output requirement | Structured case data from variable inputs | Reproducible and traceable to the exact rule that produced it |
Auditability | Not the source of court-filed numbers | A trustee or judge can check the arithmetic |
How a Case File Builds Itself From Intake to Filing
The file starts populating the moment a case opens. A pre-filled questionnaire arrives already merged from the tri-merge credit report, an eight-year filing search, property records tied to the SSN, and any documents the client uploads. The client corrects and fills gaps instead of starting from blank fields.
Bankruptcy firms automating document collection see this directly: clients photograph pay stubs and statements from their phones; the portal validates each upload in real time and flags what needs resubmitting before it reaches a paralegal's queue.
Extracted facts then flow into the schedules as part of end-to-end bankruptcy filings with Glade AI agents. A value entered once propagates across the 21-plus linked petition fields it belongs to, so income, creditors, and asset figures never get retyped between screens. By filing prep, the packet is assembled from data already read, matched, and placed.
Keeping Case Data Accurate: Conflict Detection and Human Review
Automated extraction does not mean automated trust. When the questionnaire says one income figure, the pay stubs show another, and a bank statement suggests a third. A well-built system surfaces the disagreement instead of quietly choosing. Each conflicting value carries provenance: which source it came from, when it was captured, and a confidence score, a capability made possible by specialized service agents for bankruptcy. Staff resolve it, and the confirmed value propagates to the linked fields.
That human step is not optional for anything court-filed. Attorneys and paralegals review every schedule before it becomes a petition. The limits are real too: AI struggles to read handwritten pay stubs, and credit report ingestion misses county-level judgment liens, which never appear on bureau reports. Those still need a separate title or county-records check.
How Case Intelligence Reduces Petition Rejections and Deficiency Notices
A deficiency notice starts a clock the moment the court issues it. Some must be cured in as little as 72 hours, others up to 14 days, and a missed cure can dismiss the case, per the Central District of California's guidance.
Most triggers are avoidable, as seen in how a high-volume firm tightened its workflow. The most common cause of refiles is a signature date that does not match the filing date, followed by missing district-required forms and interactive PDFs the court's system rejects.
Case intelligence catches these before submission. Signatures and dates generate at filing time, so they match the actual timestamp. District checklists block submission when a mandatory local form is missing. PDFs flatten to CM/ECF specs automatically. Each fix targets a documented rejection vector instead of waiting for the court to find it.
What to Look for When Vetting Case Intelligence Software
Run any tool against your actual caseload before signing. The checklist that matters:
- Bankruptcy-native data model, not a general legal system configured for it. A custom-built AI solution for your bankruptcy firm natively understands debtors, creditors, and schedules.
- Chapter 7 and Chapter 13 depth, including plan calculation and above-median handling.
- Parsing quality on credit reports and pay stubs across all three bureaus and varied formats.
- Deterministic statutory math for the means test and exemptions, not AI-generated numbers, a distinction covered in depth in the AI for bankruptcy law 2026 guide.
- Court-notice classification and e-filing coverage in your districts. Both vary by tool.
- Conflict detection with attorney override, so nothing court-filed gets set without human review.
How Glade AI Applies Case Intelligence to Bankruptcy Workflows
Glade AI is built bankruptcy-first around Case Intelligence: your case file builds itself as the work happens. AI agents read documents, credit reports, and forms, pre-populate 50 to 75 percent of questionnaire fields before paralegal review, and propagate a single entered value across the 21-plus linked petition fields it belongs to. A separate deterministic engine owns the means-test math, so court-filed numbers stay auditable.
That is how the 8-hour petition assembly collapses to roughly 2 hours. Conflict detection flags disagreements with source provenance; attorneys approve every schedule before filing. Automated e-filing runs in select districts, with manual PACER submission elsewhere.
Final Thoughts on Case Intelligence for High-Volume Filing
A filing cabinet with a keyboard makes your staff do the assembly, and that is where the hours and the schedule errors pile up. Case intelligence hands them a populated file to check instead, catches rejection triggers before submission, and keeps the means-test math auditable. You still hold the final review on everything court-filed. See how Glade automates petition prep for your firm.
FAQs
Which bankruptcy software can replace Best Case, Clio, and Court Drive in one system?
Tools like Best Case, Clio, and Court Drive each have genuine strengths, and they work well for the firms built around them. Best Case is the industry-standard petition-assembly tool for firms whose primary need is OneTouch filing. Clio is a strong fit for general or mixed-practice firms that need broad case management across multiple practice areas. Court Drive suits firms that want dedicated AI-assisted docketing and eNotice management layered onto their existing stack. The friction shows up when a bankruptcy-first firm has to keep all three in sync by hand. Look for a bankruptcy-native system that owns intake, document collection, petition prep, e-filing, and court-notice routing in one workspace, so no paralegal has to keep separate tools aligned. Glade AI is built for this consolidation, though automated e-filing runs in select districts with manual PACER submission elsewhere, so confirm your districts before switching. (Competitor feature descriptions based on publicly available information as of July 2026.)
Can AI populate bankruptcy Schedules D, E, and F without manual data entry?
Yes. AI reads the tri-merge credit report semantically and routes each tradeline to Schedule D, E, or F by its function instead of the label a bureau prints, which keeps routing consistent across Experian, TransUnion, and Equifax. The limit worth knowing: credit report ingestion misses county-level judgment liens, which never appear on bureau reports and still need a separate title or county-records check.
How can a small bankruptcy firm scale case volume without hiring more paralegals?
Cut the manual keying that caps per-person caseload. When AI reads documents and pre-populates 50 to 75 percent of questionnaire fields before paralegal review, and a single entered value propagates across the 21-plus linked petition fields it belongs to, one paralegal carries more cases without the transcription burnout that stalls growth.
Why does Glade run the means test on deterministic math instead of AI?
Because a trustee or judge can check the arithmetic, and court-filed numbers need to be reproducible and traceable to the exact rule that produced them. Glade uses AI for the variable work of reading documents, then runs the means test, income averaging, and exemption limits on fixed formulas against published thresholds, so an LLM never guesses at a number that gets filed.
How does case intelligence software prevent petition rejections and deficiency notices?
It targets the documented rejection vectors before submission instead of waiting for the court to find them. Signatures and dates generate at filing time so they match the actual timestamp, district checklists block submission when a mandatory local form is missing, and PDFs flatten to CM/ECF specs automatically.